Conducting Common Hypothesis Tests
Pre-Study · Module 9 · Fri Oct 9
Welcome to the M09 pre-study. You’ve already read the M09 Module — Part 1’s “one logic, five designs” framing (the decision map, what stays fixed and what changes from test to test, the two kinds of assumptions), and the five tests M09 develops in full: the one-sample t recapped from M08, then the two-sample t, one-way ANOVA, chi-square test of independence, and paired-samples t, each walked through the same six-step template. That was the textbook treatment. This pre-study is where the recipe gets practiced.
The activities are key. Each one asks you to build a quantity by hand, predict what R will print before you run it, or read an output and say what it means.
How this page is organized
Four short videos carry the Module’s hardest conceptual moves:
- Video 1 — The machinery, and the two numbers you compare. The four ingredients, and the t* vs tobs distinction.
- Video 2 — Cohen’s d and the magnitude question. What d answers that p can’t.
- Video 3 — Where F comes from. Splitting the variance, and why the ratio is compared against 1.
- Video 4 — When the outcome is categorical. Observed versus expected, and why the deviations get squared.
Ten activities on the blorg_exp1 dataset follow, in three formats:
- ✍️ Code — a starter with blanks, plus 💡 Hint and 👀 Spoiler tabs. Work through ✍️ first; open the others only after trying it yourself.
- 🔮 Predict, then run — commit to an answer before you execute. Being wrong here is the fastest way to learn something.
- 👀 Read the output — nothing to write. A result is printed; you say what each number means, then check yourself.
Each video block ends with a Quick Check of 5–6 self-scoring items. Plan on about 75 minutes for the whole page.
Meet the data: Hofman Experiment 1
Throughout this pre-study we’ll work with blorg_exp1.Rds — the dataset from Experiment 1 of Hofman, Goldstein, & Hullman (2020). The M09 Module’s Tests 2–4 use the Experiment 2 data (blorg_exp2.Rds, with four visualization formats and two effect sizes); the Module’s Test 1 uses the same Experiment 1 data we use here. Experiment 1 is a simpler design — and a fresh testbed for the recipe.
blorg_exp1 · 1,743 observations · 6 variables · Hofman, Goldstein, & Hullman (2020), Experiment 1 · data/blorg_exp1.Rds
A 2 × 2 factorial: each Mechanical-Turk participant viewed one visualization comparing a “special boulder” (the treatment) and a “standard boulder” in the boulder-sliding cover story, then reported how much they’d pay (in Ice Dollars, 0–250) to rent the special boulder. The factors:
- Visualization — 95% confidence interval (CI) error bars, or 95% prediction interval (PI) error bars.
- Caption text — “matching” (caption describes only what the figure shows) or “extra info” (caption gives both 95% CI and 95% PI numerical bounds, regardless of figure).
That gives four conditions of roughly 400–500 participants each. Variables:
- worker_id character — Anonymized Amazon Mechanical Turk worker identifier
- condition.f factor — Four-level experimental condition crossing visualization format and caption text
- interval_CI numeric — Visualization format shown to the participant
- text_extra numeric — Whether the caption supplied information beyond the visualization
- wtp_final numeric — Willingness to pay to rent the special boulder, in Ice Dollars
- superiority numeric — Participant’s estimate of the probability that the special boulder out-slides the standard one
Full codebook for blorg_exp1 — values, levels, missingness, and how the file was prepared.
What the participants actually saw
Every participant met the same underlying result — the special boulder slides an average of 104 m against the standard boulder’s 100 m. What changed between conditions was how that result was drawn, and what the caption told them.
Two things are worth noticing as you click through. First, the two charts plot the same data — only the error bars differ, and the y-axes are on very different scales as a result. Second, the “extra info” captions don’t add new findings; they simply state both numbers in words, whichever chart is on screen.
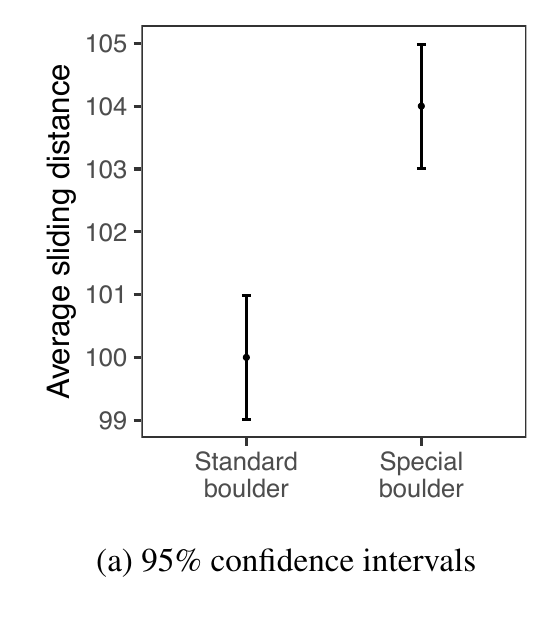
The caption gave the average and the confidence interval — matching what the figure showed:
- Your average sliding distance with the special boulder: … you would attain an average distance of 104 meters.
- Uncertainty in estimating your true average sliding distance: … a 95% confidence interval on your average is 103 to 105 meters …
Same figure, but the caption also spelled out the spread of individual slides — information the chart itself never showed:
- Your average sliding distance with the special boulder: … you would attain an average distance of 104 meters.
- Variation in your sliding distances with the special boulder: … 95% of your next 1,000 slides would be between 74 and 134 meters …
- Uncertainty in estimating your true average sliding distance: … a 95% confidence interval on your average is 103 to 105 meters …
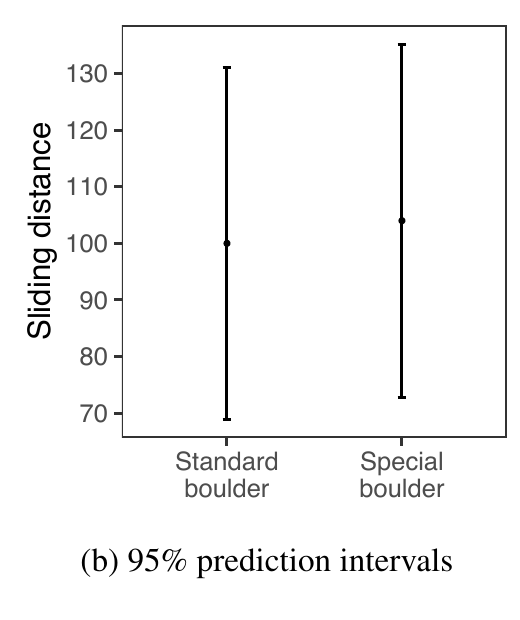
The caption gave the average and the prediction interval — matching what the figure showed:
- Your average sliding distance with the special boulder: … you would attain an average distance of 104 meters.
- Variation in your sliding distances with the special boulder: … 95% of your next 1,000 slides would be between 74 and 134 meters …
Same figure, but the caption also gave the confidence interval on the average:
- Your average sliding distance with the special boulder: … you would attain an average distance of 104 meters.
- Variation in your sliding distances with the special boulder: … 95% of your next 1,000 slides would be between 74 and 134 meters …
- Uncertainty in estimating your true average sliding distance: … a 95% confidence interval on your average is 103 to 105 meters …
Look at the two charts side by side and the finding almost explains itself. The CI chart’s y-axis runs from 99 to 105, so a 4-metre difference fills the frame and the two boulders look decisively different. The PI chart’s runs from about 70 to 135, and the same 4-metre difference nearly vanishes inside two heavily overlapping intervals. Same data, same difference — opposite impressions. That is the effect you are about to measure.
(Figures and caption wording from the authors’ own design materials for Experiment 1.)
Hofman et al.’s headline finding from Experiment 1: participants who saw a CI plot were willing to pay substantially more for the special boulder than participants who saw a PI plot. In the matching-text condition the gap was $29.37, Cohen’s d ≈ 0.57. The extra-info condition narrowed it (d ≈ 0.36) but did not close it. The visualization changed how readers perceived the size of the underlying effect — even when the same numerical information appeared in the caption.
You’ll re-derive these numbers yourself. Below the videos the dataset is available as blorg_exp1, with pre-built subsets mt (matching text) and et (extra info).
Video 1 — The machinery, and the two numbers you compare
📹 Video 1: The Machinery, and the Two Numbers You Compare
~6 min · [video will be embedded here]
What to listen for:
- Every test statistic in M09 does the same job: it measures how far the data depart from H₀, relative to the departures the null model ordinarily produces. The arithmetic differs by test — a t is literally a gap over its standard error, while F and χ² aggregate departures in their own ways.
- The four ingredients — test statistic, reference distribution, critical value, decision rule. All four are present in every test.
- The two symbols that get confused. \(t^*\) is the critical value — the threshold your decision rule sets. \(t_\text{obs}\) is your statistic, computed from your sample. The asterisk marks a threshold; the “obs” subscript marks your result. What you fix before seeing the result is the convention: \(\alpha = .05\), two-sided, a t reference curve. The exact number \(t^*\) takes also depends on the degrees of freedom — and for Welch’s test those are computed from the observed group variances, so the final numerical \(t^*\) arrives only once you have the data.
- Degrees of freedom usually come from counting: quantities you started with, minus constraints they must satisfy. That idea generates the df for the one-sample t, the paired t, ANOVA, and chi-square. Welch’s fractional df is the deliberate exception — an approximation that reshapes the reference curve to account for two separately estimated variances.
- For the two-sample t, \(SE_\text{diff}\) has two forms (Welch and Student); default to Welch’s, because R does and because it doesn’t assume equal variances. Welch’s df is non-integer — a weighted blend of the two groups’ contributions.
Activity 1.1 — Build the statistic ✍️
The matching-text subset is pre-built as mt (the rows where text_extra == 0). Its descriptives are below — read them carefully, because the next two activities run on them.
Your task: build the two pieces of the fraction. The gap is \(\bar{x}_{CI} - \bar{x}_{PI}\); the Welch standard error of the difference is \(SE_\text{diff} = \sqrt{s_{CI}^2/n_{CI} + s_{PI}^2/n_{PI}}\).
Four blanks. Read the two condition means off the table above (m_ci is the interval_CI == 1 mean). The two \(SE_\text{diff}\) blanks each take a group’s variance — the SD squared, not the bare SD.
The CI mean sits in the row where interval_CI == 1; the PI mean in the row where it is 0. The variance term for each group is that group’s SD squared — sd_ci^2 and sd_pi^2.
You should get a gap of about $29.37 and a standard error of about $3.43.
Think before you read on
Cover the answer and work this out in your head first.
The gap is about $29.37. The standard error of that gap is under $4. But the within-group SDs are roughly $50 — far bigger than the gap itself. How can \(SE_\text{diff}\) be so much smaller than the SDs it was built from?
Tip👀 Discussion
Because \(SE_\text{diff}\) is the standard error of a mean difference, not of an individual observation. The variance of each group’s mean is \(s^2/n\), not \(s^2\) — and dividing by an \(n\) in the hundreds shrinks it hard:
\[ SE_\text{diff} = \sqrt{\frac{s_{CI}^2}{n_{CI}} + \frac{s_{PI}^2}{n_{PI}}} \]
So \(SE_\text{diff}\) inherits the \(1/\sqrt{n}\) shrinkage from each mean. The statistic comes out large because we measured the gap precisely — not because the raw gap is unusually big. Hold onto that — it is exactly the point Video 2 makes about p versus d.
Activity 1.2 — Where t* comes from ✍️
Now the other number. The critical value \(t^*\) is a property of your decision rule, not your data: it needs only \(\alpha\), the reference distribution, and the degrees of freedom. qt() returns it.
Your task: two blanks — the quantile for a two-sided \(\alpha = .05\), and the df. Then the loop shows what df actually does.
Two-sided \(\alpha = .05\) puts \(\alpha/2 = .025\) in each tail, so the quantile you want is \(1 - .025 = .975\). The df is the welch_df assigned on the first line.
Our \(t^* \approx\) 1.963. And watch the ladder: at df = 3 the critical value is 3.182, at df = 30 it is 2.042, and by df = 500 it has settled at 1.965 — the 1.96 you know from M06’s Empirical Rule. At the same \(\alpha\), fewer degrees of freedom mean a larger critical value — and that isn’t a rule anyone imposed: it is the shape of the curve. Notice what did and didn’t come from the data here. The convention (\(\alpha = .05\), two-sided, a t curve) was fixed in advance. The df was not: welch_df is the 861.2 the Welch–Satterthwaite formula produces from the two observed group variances you used in Activity 1.1 — Activity 1.2 handed it to you ready-made. So the ladder above is a property of the t family, but our particular \(t^*\) still had to wait for the sample.
Activity 1.3 — Read the output 👀
Nothing to write here. Run the chunk, then answer the questions below it before opening the discussion.
Three questions, from the printed row:
- Which column is \(t_\text{obs}\), and how does it compare to the \(t^*\) you computed in Activity 1.2?
- How does
p_valuecompare to \(\alpha = .05\)? - Do
lower_ciandupper_cicontain zero?
Tip👀 Discussion
statistic is \(t_\text{obs} \approx\) 8.57, against \(t^* \approx\) 1.963 — past the threshold by a factor of more than four. p_value is far below .05. And the interval on the mean difference sits entirely above zero.
Those are three readings of one decision, and they agree. Not by luck, and not as three pieces of corroborating evidence — by construction. The p-value is defined as the tail area beyond \(t_\text{obs}\), so \(|t_\text{obs}| \ge t^*\) and \(p \le \alpha\) are the same statement written two ways. The 95% interval is the set of null values that wouldn’t be rejected at \(\alpha = .05\), so “the interval excludes zero” is that same statement again.
The practical consequence: if these three ever disagree in your own output, you have made an error — a one-sided test compared against a two-sided critical value, mismatched df, or a confidence level that isn’t \(1 - \alpha\). It is a free correctness check, and worth running every time.
Quick Check
Answer each question — you’ll see green (correct) or pink (incorrect) feedback as you type.
1. What does tobs represent in a two-sample t-test?
2. Which of these is needed to compute t*, the critical value?
3. As degrees of freedom increase, t* for a two-sided α = .05 test moves toward what value?
4. True or false: Welch’s degrees of freedom is not an integer because it is a weighted blend of the two groups’ contributions to the standard error of the difference.
5. A two-sided t-test and its matching 95% t-interval are run on the same comparison. tobs exceeds t*, but the interval contains zero. What is the most likely explanation?
Video 2 — Cohen’s d and the magnitude question
📹 Video 2: Cohen’s d and the Magnitude Question
~5 min · [video will be embedded here]
What to listen for:
- A p-value answers “how incompatible is this with the null model?” — and because incompatibility depends on precision, it shifts with sample size. Cohen’s d answers a different question: how big is the gap?
- The construction is one small change from the test statistic: divide by the standard deviation (how much individual people differ) instead of the standard error (how much a sample mean wobbles). The SE shrinks as \(n\) grows; the SD does not.
- Two translations travel with d: percent overlap and the common-language effect size (the chance a random member of the higher group outscores a random member of the lower group). Even a “large” d leaves the distributions heavily overlapping.
- Cohen’s benchmarks are conventions, not measurements. What counts as large depends on the setting; prior work on your own question is the better yardstick.
- Lead with the raw difference. Ice Dollars are a unit people already understand. Standardize when you need to compare across measures or pool across studies — but report raw units first.
- Sign watch: cohens_d() subtracts in factor-level order. With interval_CI coded
0/1, the default gives a negative d. Relevel so CI (1) comes first.
Activity 2.1 — Compute d, then translate it ✍️
Video 1 found strong evidence against equal population means. Now: how big is the gap?
Build the denominator by hand first — the pooled standard deviation, which is the two group SDs combined, weighted by their df:
\[ s_\text{pooled} = \sqrt{\frac{(n_{CI}-1)s_{CI}^2 + (n_{PI}-1)s_{PI}^2}{n_{CI} + n_{PI} - 2}} \]
Your task: three blanks — the pooled-SD denominator, the divisor that turns the gap into d, and the factor-level order that makes d positive.
The pooled-SD denominator is the total degrees of freedom, n_ci + n_pi - 2. Cohen’s d is the gap over the pooled SD — so s_pooled goes in the second blank. For the sign, list 1 (CI) before 0 (PI).
Your hand calculation and cohens_d() should agree: d ≈ 0.57, 95% CI [0.44, 0.71]. Note the pooled SD is about $51.13 — roughly fifteen times the $3.43 standard error from Activity 1.1. Same gap on top; a very different denominator underneath. That single swap is the whole difference between a test statistic and an effect size.
One refinement, because it will come up in the lab. The pooled SD you just built weights the two group variances by their degrees of freedom — and in doing so it assumes the two populations share a variance. But the test you ran in Video 1 was Welch’s, which pointedly refuses that assumption. Pairing them isn’t a disaster, but it does quietly smuggle back in the thing Welch avoided.
cohens_d() lets you say so. Setting pooled_sd = FALSE standardizes by \(\sqrt{(s_{CI}^2 + s_{PI}^2)/2}\) instead — the two SDs combined without weighting by n, and without any equal-variance claim:
Here the two agree to two decimals, because the groups are close to the same size and spread. That is not guaranteed — the more the group sizes or SDs differ, the further apart they drift.
The course rule for Cohen’s d
Two standardizers, two jobs, and you should never leave a reader guessing which one you used.
- Building it by hand — use the pooled SD, as you just did. It is the classical form, it is what Hofman et al. report, and it is what “Cohen’s d” means without further qualification.
- Reporting a d beside a Welch test — use
pooled_sd = FALSE. The test already refused the equal-variance assumption; the effect size should not quietly reinstate it. This is what effectsize’s own documentation recommends (Delacre et al., 2021), and it is what the M09 lab uses.
Either way, name the standardizer when you write it up. The rest of this page keeps working with the pooled value so the arithmetic stays continuous with what you built by hand — and because with groups this similar, the choice moves nothing.
Now translate the pooled 0.57 into something you could say to a non-statistician. These two formulas are derived for a conventional, equal-variance standardized difference, which is exactly why we apply them to the pooled value rather than the unpooled one:
Read both of those as model translations, not measurements. Each formula describes two equal-variance Normal populations separated by d; our WTP scores are bounded at 0 and 250, right-skewed, and heaped on round numbers, so these are what a d of 0.57 would imply under that model — not a tally of the observed distributions.
Under that model, the two distributions share about 77% of their ground, and the probability that a randomly selected CI viewer has the higher WTP is about 66% — up from the 50% you’d see if the display made no difference, but nowhere near certainty. An average difference is entirely compatible with enormous individual variation. That is the most useful thing an effect size will teach you, and it is invisible in the p-value.
Does spelling out the numbers in the caption close the gap? Rerun on the extra-info subset:
Here d ≈ 0.36, 95% CI [0.22, 0.49] — descriptively smaller than 0.57, and still comfortably clear of zero. Be careful how you say this. Comparing two separately estimated effect sizes does not test whether the caption changes the visualization’s effect; that is an interaction, and it needs a factorial model this Module doesn’t fit. What you can say is that the CI−PI gap is smaller when the caption spells out both numbers, and that it does not vanish. The picture is still doing work the words don’t undo — which is Hofman et al.’s point.
Activity 2.2 — Same d, different n 🔮
Predict first. Below, the effect is pinned at d = 0.57 and only the sample size changes. Before you run anything, commit to an answer:
As n per group goes from 30 to 100 to 450, what happens to (a) the t-statistic, (b) the p-value, and (c) Cohen’s d?
Write it down — actually write it down — then run the chunk.
Tip👀 How did you do?
At 30 per group the t is about 2.2 and p ≈ .03 — significant, but only just. At 450 per group t is past 8 and p is vanishingly small. And d never moves, because we pinned it.
The formula shows why: \(t = d \times \sqrt{n/2}\). The test statistic is the effect size multiplied by a function of sample size. They are not competing measures of the same thing — one is the effect, the other is the effect scaled by how well you measured it.
Two consequences worth carrying:
- A tiny p-value does not mean a large effect. It can mean a modest effect measured very precisely — which is exactly our 905-participant study.
- A non-significant result does not mean no effect. At n = 30 per group, a genuine d of 0.57 lands near the edge; a slightly smaller one would have missed entirely. That’s a statement about the study’s precision, not about the world.
Quick Check
Answer each question — you’ll see green (correct) or pink (incorrect) feedback as you type.
1. In the conventional two-sample Cohen’s d you built by hand in Activity 2.1, the gap between the means is divided by what?
2. Why does Cohen’s d not shrink as the sample grows, when the p-value does?
3. Under an equal-variance Normal model, our d of about 0.57 implies the two distributions overlap by roughly 77%. What does that tell you?
4. A colleague reports p < .001 and no effect size. What have they not told you?
5. True or false: Cohen’s benchmarks (0.2 small, 0.5 medium, 0.8 large) are conventions offered for when you have no better basis for comparison, not fixed properties of the numbers.
Video 3 — Where F comes from
📹 Video 3: Where F Comes From — Splitting the Variance
~8 min · [video will be embedded here]
What to listen for:
- With three or more groups, the t gives way to the one-way ANOVA’s F.
- Total variation splits exactly into two pieces: variation of the group means around the grand mean (between), and variation of individuals around their own group’s mean (within). \(SS_\text{total} = SS_\text{between} + SS_\text{within}\) is an identity, not an approximation.
- You cannot compare the two sums directly — they are built from different numbers of free quantities. Divide each by its df to get a mean square, and then they are comparable.
- \(F = MS_\text{between} / MS_\text{within}\). When H₀ is true both mean squares estimate the same thing, so the ratio hovers near 1 — that is why 1, not 0, is the reference point.
- The F is an omnibus test: it says at least one group differs, not which. Tukey’s HSD answers “which,” holding the familywise error rate at α across all pairs. It is not gated on a significant F.
- ANOVA’s effect size is η², the share of total variation attributable to group membership.
Activity 3.1 — Split the variance by hand ✍️
The full design has four conditions in condition.f. Build the partition yourself, then confirm the identity closes.
Your task: three blanks — the two SS formulas and the comparison that checks the identity. Note the weight \(n_j\) in \(SS_\text{between}\): a group’s deviation counts once for every person in it.
\[ SS_\text{total} = \sum_i (y_i - \bar{y})^2 \qquad SS_\text{between} = \sum_j n_j(\bar{y}_j - \bar{y})^2 \]
\(SS_\text{total}\) measures every observation’s distance from the grand mean. \(SS_\text{between}\) weights each group’s squared deviation by that group’s size — the n column in group_stats. And the identity to check is that ss_between plus ss_within recovers ss_total.
The grand mean is $63.60, and the split is \(SS_\text{total} =\) 4,850,914 \(=\) 265,094 \(+\) 4,585,820. all.equal() returns TRUE.
Look at the relative sizes. Almost all the variation in what people were willing to pay is within conditions — person-to-person differences that the experiment doesn’t explain. The between-groups piece is the small remainder that condition membership accounts for. Note the wording: this model has one four-level factor, so it speaks about conditions, not about the visualization and the caption separately. That ratio is what the F-test is about to formalize, and it is also a preview of the η² you’ll compute in a moment.
Activity 3.2 — From sums of squares to F ✍️
You cannot compare ss_between to ss_within directly: one is built from 4 group means, the other from 1,743 observations. Divide each by its degrees of freedom — quantities minus constraints, the same counting rule from Video 1 — and the two become comparable.
Your task: three blanks — the two df, and the ratio.
With k groups constrained by one grand mean, df_between is k - 1. With n_total observations constrained by k group means, df_within is n_total - k. And F puts the between mean square on top.
Your hand-built F and R’s table agree: F(3, 1,739) = 33.51, p < .001.
Notice the reversal that dividing by df produced. \(SS_\text{within}\) (4,585,820) is roughly seventeen times \(SS_\text{between}\) (265,094) — on the raw sums, the within-group variation dwarfs everything. But \(MS_\text{between}\) (88,365) is about thirty-three times \(MS_\text{within}\) (2,637). The sums of squares and the mean squares point in opposite directions, which is precisely why you cannot skip the df step.
So the display matters — but how much? That is η²: the share of total variation that group membership accounts for.
η² ≈ 0.055, 95% CI [0.035, 0.076] — the four-level condition factor accounts for about 5.5% of the sample variation in willingness to pay. Set that next to p < .001 and the contrast is the whole lesson of Video 2 again: an effect can be nearly impossible to attribute to sampling variation and still be a small slice of what’s going on. With 1,743 participants, we can detect a 5.5% share with great confidence. Confidence and importance are different questions.
The F is an omnibus test — it says at least one of the four conditions differs, not which. Tukey’s HSD answers that, and controls its own familywise error rate across all six pairs:
Read the pattern rather than the individual rows. Every CI-versus-PI cell comparison is statistically detectable at Tukey’s familywise level; neither within-visualization caption comparison is. So the largest separations follow the CI-versus-PI contrast.
Say that carefully. This is a 2 × 2 design analyzed as one four-level factor, so the model never estimated a visualization main effect, a caption main effect, or an interaction. Describing which cell pairs separate is honest; concluding that “the visualization matters and the caption doesn’t” would be reading a factorial result out of a model that cannot produce one. Testing those three things directly needs a factorial ANOVA — a PSY 653 topic. Keep the pattern in mind; Video 4 finds it again in a different test.
Activity 3.3 — What F looks like when nothing is going on 🔮
Video 3 claims F hovers near 1 when H₀ is true. Here you check it.
The chunk below draws four groups of 100 from a single population — so there is no real difference to find, by construction. It does that eight times.
Predict first. Before running: what will those eight F values look like? Will any exceed the critical value \(F^* =\) 2.63? Commit to an answer.
Now run many more and look at the shape:
Tip👀 How did you do?
The eight values scatter below and around 1, and none of them comes near 2.63 — even though every one came from a dataset with no real group difference at all.
Across 300 runs the average lands just under 1 — close, with the remaining wobble being sampling variation across 300 runs rather than a bias. The target it is wobbling around is exact: when H₀ is true, \(MS_\text{between}\) and \(MS_\text{within}\) are two independent estimates of the same population variance, so the ratio has an expected value of \(df_\text{within}/(df_\text{within} - 2)\) — here 1.0051.
That is the answer to “why compare F to 1.” It isn’t a convention; it’s what the ratio of two estimates of the same quantity has to do.
Two more things in that histogram worth naming:
- It is right-skewed, not symmetric. F cannot go below zero but has no upper bound, so the null distribution piles up near 1 with a long right tail. That is also why the F-test uses only the upper tail — a small F is not evidence of anything interesting.
- A few runs land past the dashed line. Roughly one in twenty, which is α doing exactly what it advertises. Those are false positives generated from a world with no effect. Against that backdrop, our real F of 33.51 is in a different regime entirely.
Quick Check
Answer each question — you’ll see green (correct) or pink (incorrect) feedback as you type.
1. What does the ANOVA’s F-ratio compare?
2. Why must sums of squares be converted to mean squares before they are compared?
3. When H₀ is true, F is centered near 1. Why 1 rather than 0?
4. Our ANOVA gave p < .001 with η² ≈ 0.055. What is the right read?
5. True or false: Tukey’s HSD may only be run after the omnibus F comes out significant.
6. Experiment 1 crossed two factors — visualization (CI/PI) and caption (matching/extra). True or false: because our one-way ANOVA covers all four conditions, it tells us whether the visualization’s effect depends on which caption a reader saw.
Video 4 — When the outcome is categorical
📹 Video 4: When the Outcome Is Categorical
~6 min · [video will be embedded here]
What to listen for:
- Two symbols run every chi-square test: O, the count you observed, and E, the count expected if the null were true.
- The margins do double duty. They generate the expected counts (row total × column total ÷ overall total), and they fix the degrees of freedom at \((r-1)(c-1)\).
- Why the deviations are squared. The raw deviations \(O - E\) always sum to exactly zero, because observed and expected counts share the same total, so adding them up would always give nothing. Squaring makes every cell contribute positively — absolute values would too, but squaring is what produces Pearson’s statistic, the one whose large-sample reference curve is the chi-square distribution. It is also why chi-square has no direction and no one-sided option.
- Dividing by E scales each squared deviation against the size of the cell it came from. Being off by 20 counts is a bigger deal where only 30 were expected than where 3,000 were — dividing by E is what encodes that.
- The adequacy check is on the expected counts, not the observed: none below 1, no more than about 20% below 5.
- Standardized residuals show which cells carry the association — roughly standard Normal under independence, so beyond about ±2 is worth reading. Treat that as a way of describing the pattern, not as a set of formal tests.
Before we cut a continuous variable in two
Willingness to pay is measured in dollars. Turning it into a yes/no throws information away, and we are doing it here to practice the categorical test, not because it improves on the analyses you just ran.
The one defensible reason to dichotomize is a substantively meaningful cutpoint — and Experiment 1 supplies one. The upgrade’s risk-neutral price is $17.50: that is the most it is worth in expected winnings. Paying more means paying above what a risk-neutral player should — which is a precise, model-based statement, not a verdict that the person was irrational. Someone who enjoys the gamble, or who weights a big win more heavily than its probability, may rationally pay more. Throughout this section, read “overpaid” as shorthand for above the risk-neutral benchmark.
Cutting at a convenient round number instead ($50, say, because it looks like a reasonable slice of the $250 prize) is how dichotomization earned its bad reputation. The number has to come from the problem, not from the keyboard.
Activity 4.1 — Build the cross-tab ✍️
Your task: three blanks — the two arms of the split at the risk-neutral price, and the percentage direction. Row percentages are what make the null hypothesis legible here.
Both arms cut at the risk-neutral price, 17.50 — strictly above it is overpaying, at or below it is not. For the percentages, you want each condition to sum to 100%, so the direction is "row".
Overall, 81% of participants paid above the risk-neutral benchmark. But read down the rows: 89% and 85% for the two CI conditions, against 74% and 75% for the two PI conditions.
That is the null hypothesis made visible. Independence is the claim that all four row percentages are equal — that knowing someone’s condition tells you nothing about whether they overpaid. The rows are clearly not equal; the test asks whether they are further apart than sampling variation would ordinarily produce.
Activity 4.2 — Test independence, then find the cells ✍️
Activity 4.1 showed the row percentages drifting apart — 89% down to 74%. This activity asks whether that drift is more than sampling variation would ordinarily produce, and if so, which cells are responsible.
Three pieces of output do three different jobs, and it’s worth knowing what you’re looking for before you run it:
- The test itself gives χ², its df, and a p-value. Remember what the null says: all four row percentages are equal — knowing someone’s condition tells you nothing about whether they overpaid.
- The expected counts are the adequacy check. They are what each cell would hold if the null were true, computed from the margins, and they’re what the rule of thumb applies to — not the counts you observed.
- The standardized residuals say where the association lives. Each one is roughly a z-score for its cell under independence, so values beyond about ±2 mark the cells pulling hardest. Read them as a description of the pattern rather than as eight separate tests.
Your task: three blanks — the two variables that get crossed, and the component holding the expected counts.
Cross the predictor condition.f with the categorical outcome overpaid, in that order, so conditions stay on the rows. The expected counts live in the component literally named expected.
χ²(3, N = 1,743) = 45.27, p < .001, Cramér’s V ≈ 0.16, 95% CI [0.1, 0.2].
Three things to read, in order:
The adequacy check passes comfortably. Applying the guideline from the video — none below 1, no more than about 20% below 5 — the smallest expected count here is 78.0, far clear of it. The large-sample chi-square approximation is clearly reasonable here, so no Fisher’s exact test is needed.
The residuals name the pattern. Both CI conditions sit positive on “Overpaid” and both PI conditions sit negative, with the largest magnitude around 4.74. So the association runs along the CI-versus-PI split, with the caption text adding little. That is the same descriptive pattern Tukey’s HSD showed in Video 3 — though note it is not independent confirmation: it is the same willingness-to-pay data, re-expressed as a yes/no after discarding the amounts.
The effect is modest. By the usual conventional benchmarks — which, like Cohen’s, are conventions rather than measurements — Cramér’s V of 0.16 is a modest association, and note it is the bias-adjusted form (that is what adjust = TRUE requests), which is why it differs slightly from the textbook \(\sqrt{\chi^2 / (N(k-1))}\).
Quick Check
Answer each question — you’ll see green (correct) or pink (incorrect) feedback as you type.
1. In a chi-square test, where do the expected counts come from?
2. Why does Pearson’s chi-square square the O − E deviations rather than simply adding them up?
3. Each squared deviation is divided by that cell’s expected count. Why?
4. Before trusting a chi-square test of independence, what should you check?
5. True or false: we cut willingness to pay at $17.50 because it is the risk-neutral price of the upgrade, so the split means “did this participant pay above the risk-neutral benchmark?”
Wrap-up
Four things to carry into lecture
- The recipe generalizes; only the filling-in changes. A test statistic, a reference distribution, a critical value, a decision rule — that skeleton held while the design moved from two groups to four to a categorical outcome. You built the t by hand, then the F from its own sums of squares, and the shape was the same both times.
- t* and tobs are different animals, and the three readings of a test — statistic against critical value, p against α, interval against the null value — agree by construction. When they don’t, you have found a mistake, not a puzzle.
- Significance and magnitude are separate questions. Our ANOVA reached p < .001 on an η² of 0.055, and pinning d at 0.57 while dialing n moved the p-value across three orders of magnitude. Report both, and lead with the raw units.
- Every test here handles one factor at a time. Experiment 1 crossed two factors — visualization and caption — but a one-way ANOVA on the four cells tests only whether the four condition means are all equal. It cannot isolate a visualization effect, a caption effect, or an interaction between them; that needs a factorial model, which is a PSY 653 topic. Describing the pattern across cells is honest. Attributing it to one factor is not.